


You need a competitive analysis on three companies before a strategy meeting on Thursday. You have skills for this. A research skill that pulls pricing, features, and funding data. A curation skill that organizes raw findings into a comparison grid. An analysis skill that writes the narrative. A formatting skill that polishes everything into a send-ready report.
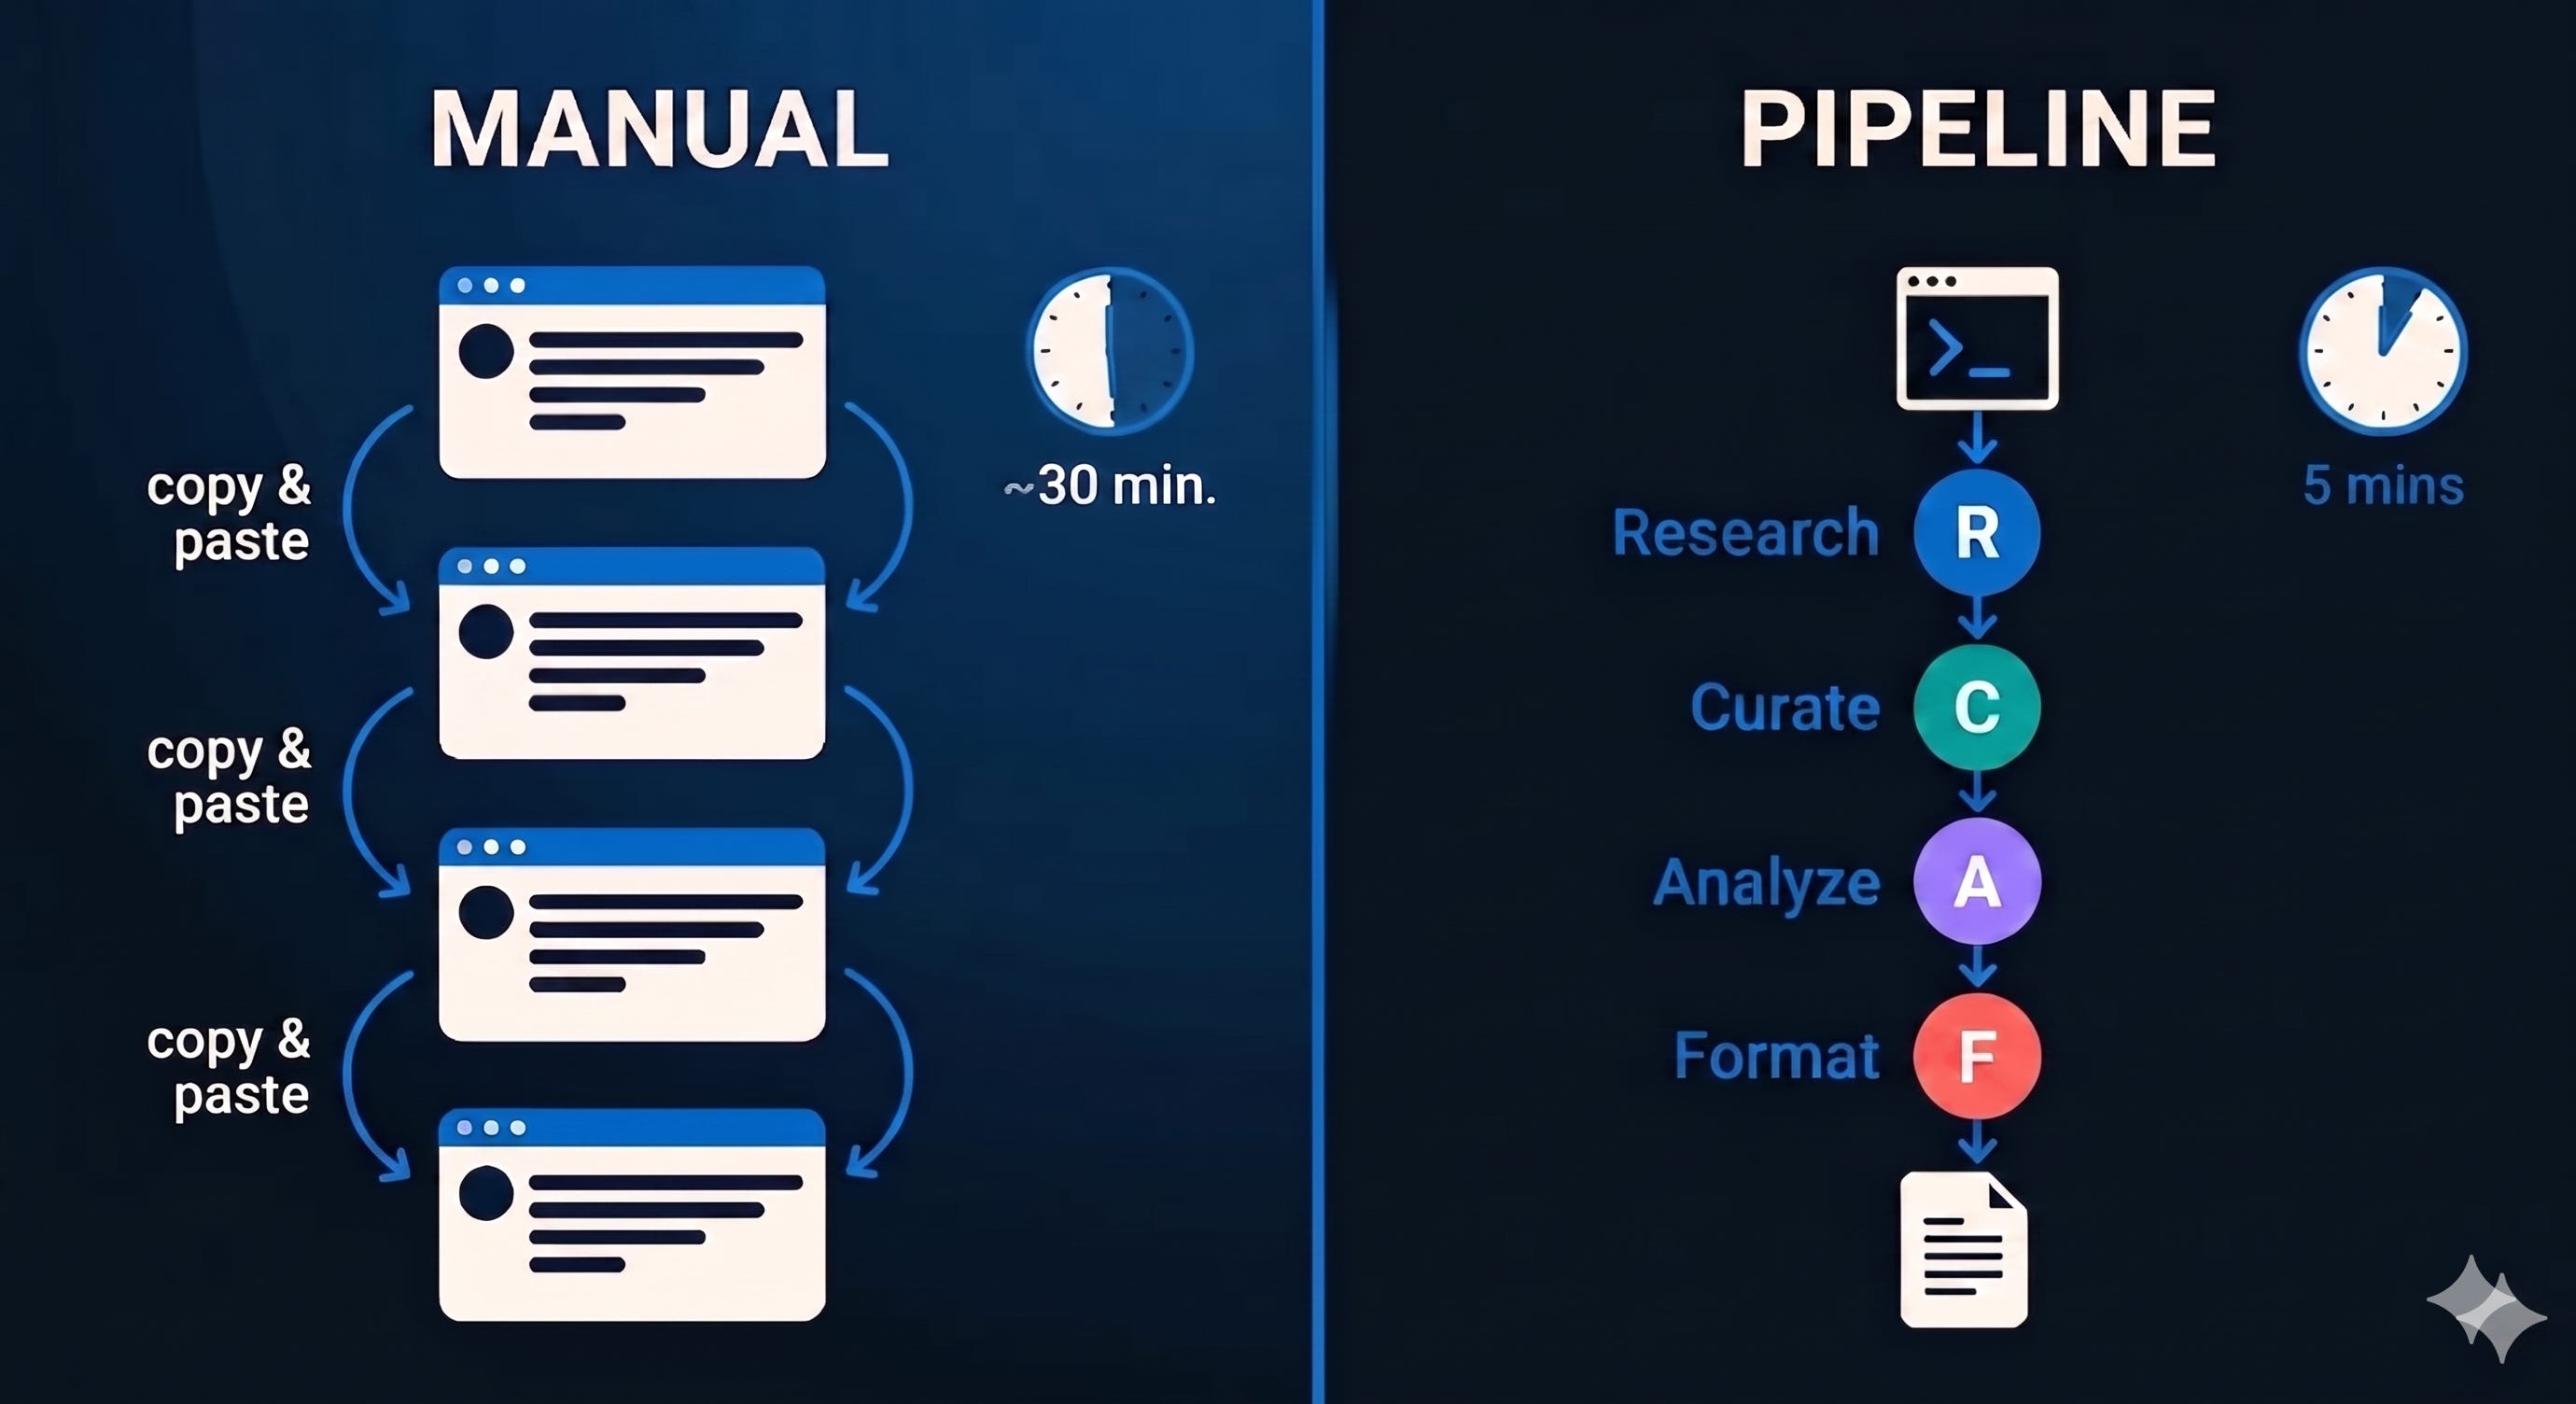
You trigger /competitor-research. Wait for it to finish. Read the output. Now you need to run the curation skill, but the research output for three companies already filled a significant chunk of your context window. The curation skill needs to process all that data, consuming even more tokens. By the time you get to the analysis skill, your context is packed with thousands of tokens of intermediate processing. The quality starts to drift. Formatting gets inconsistent. Claude starts losing track of earlier details.
So you try the alternative: copy the research output, open a new chat to save tokens, paste it in, run the curation skill there. Then copy that output, open another chat, paste it in, run the analysis skill. Then again for formatting.
Four chats. Four copy-pastes.
Either way, you’re the middleware. You’re the one managing the handoffs, carrying context between skills, deciding when to start a new chat. The skills are fast. You are the bottleneck.
What if you typed one command, walked away, and came back to a finished competitive intelligence report? Four skills firing in sequence. No copy-pasting. No context decay. The pipeline manages its own handoffs, runs autonomously, and delivers the final output when it’s done.
That’s what this article builds
What’s Ahead…
A primer on Claude Code skills: what they are and how the YAML works
The orchestrator pattern: chaining skills into one autonomous pipeline

A Quick Primer on Claude Code Skills
If you’ve never built a skill, here’s what you need to know. A skill is a markdown file with two parts.
If you want a full walkthrough on Claude Skills before we get into chaining, check out our previous article 👇

Part 1: YAML frontmatter. This is the metadata block at the top of the file, wrapped in --- lines. It contains the skill’s name, a description of what it does, and configuration settings that control how Claude runs it. Think of it as the label on the outside of the box.
Part 2: Markdown instructions. Everything below the frontmatter. This is what Claude reads and follows when you trigger the skill. It can be as simple as three sentences or as detailed as a multi-page operating manual.
Here’s what a basic skill file looks like:
---
name: meeting-prep
description: Prepares a briefing document for an upcoming meeting
---

Research the company and attendees for the meeting described below.
Pull recent news, LinkedIn profiles, and any previous correspondence.
Produce a one-page briefing with: attendee bios, company snapshot,
three conversation starters, and any open items from past meetings.
You save this as a Claude skill. In Claude Code, slash commands run skills. Type /meeting-prep and Claude reads the file, follows the instructions, and delivers the output. A skill can do anything you can describe in plain English: research a topic, draft a document, analyze data, format a report, pull information from Notion or Slack through MCP (Model Context Protocol, which connects Claude to your external apps and data).
The Frontmatter Fields That Matter
That basic example uses minimal frontmatter: just a name and description. But the YAML block can do more. Here are the fields you need for building pipelines:
---
name: competitor-research
description: Researches a single company
context: fork
agent: general-purpose
disable-model-invocation: true
allowed-tools: WebSearch WebFetch Read Write Skill
---

Research the following company: $ARGUMENTS
Each field plays a distinct role:
nameanddescription: The basics. The name becomes your slash command. The description tells Claude when to suggest it.context: fork: Runs the skill in a separate, isolated subagent with its own context window. Your main session stays clean. Only the final output comes back. Without this, all processing piles up in your conversation. A four-skill pipeline can produce 15,000+ tokens of intermediate work you never need to see. This field keeps it out of your way.agent: general-purpose: Tells the subagent what tools it can access.general-purposegives full access: reading and writing files, web search, and calling other skills. Other options:Explore(read-only research) andPlan(read-only planning).disable-model-invocation: true: Prevents Claude from triggering this skill on its own. It runs only when you type the slash command manually. Important for pipelines you don’t want firing accidentally.allowed-tools: Pre-approves specific tools so Claude doesn’t pause mid-task to ask your permission. If your skill calls other skills, this list must includeSkill. If it does web research, includeWebSearchandWebFetch. If it connects to Notion via MCP, include the MCP tool names.$ARGUMENTS: This one sits in the instructions section, below the frontmatter. It’s a built-in variable that captures everything you type after the slash command./competitor-research "Anthropic"sets$ARGUMENTSto"Anthropic"./competitive-intel "Anthropic" "Google" "Perplexity"sets it to"Anthropic" "Google" "Perplexity". This lets you reuse the same skill with different inputs every time.
You don’t need all these fields for a basic skill. The meeting-prep example works fine with just name and description. But when you start chaining skills into pipelines, these fields are what make it work.
A note on where this works: Claude Code runs in your terminal (Mac, Windows, Linux). Skills and everything in this article require Claude Code. If you’ve only used Claude through the web app or desktop app, you’ll need to install Claude Code first. It’s free to install. You need a Claude Pro or Team subscription for the model usage.
If you are new to Claude Code, setting up is easy, check out my previous article for details and also the best non-technical use case for Claude Code

A Quick Note on File Formats (And the Mistake That Cost Me 20 Minutes)
When I first built a skill, I asked Claude to save it as test-chain.skill. The slash command never showed up in autocomplete. Turns out Claude Code accepts two file formats and only one triggers via /.
.md: Plain markdown file. Triggers via slash command. Use this..skill: Packaged zip bundle. Claude can invoke it on its own, but no slash command.
Every skill in this article is .md. Any .skill files you already have from plugins or marketplaces still work; they just don’t show up when you type /.
From Single Skills to Skill Chains
A skill can call other skills. That’s the concept.
An orchestrator is a skill file that contains a sequence of /skill-name commands instead of a single task. When you trigger the orchestrator, Claude runs Skill A, takes the output, feeds it into Skill B, takes that output, feeds it into Skill C. Each stage has full access to everything the previous stage produced. One command in, one finished deliverable out.
The orchestrator file looks exactly like any other skill. Same format. Same YAML frontmatter. Same markdown instructions. The only difference: instead of instructions for a single task, it contains a step sequence.
Here’s where it gets interesting. Add one line to the orchestrator’s YAML frontmatter:
context: forkThis tells Claude Code to run the entire pipeline in a separate, isolated subagent. Think of it as a background worker with its own context window. Your main chat session stays clean. The orchestrator fires up this separate worker, runs all four skills in sequence inside it, processes all the intermediate output internally, and when the pipeline finishes, only the final result comes back to your session.
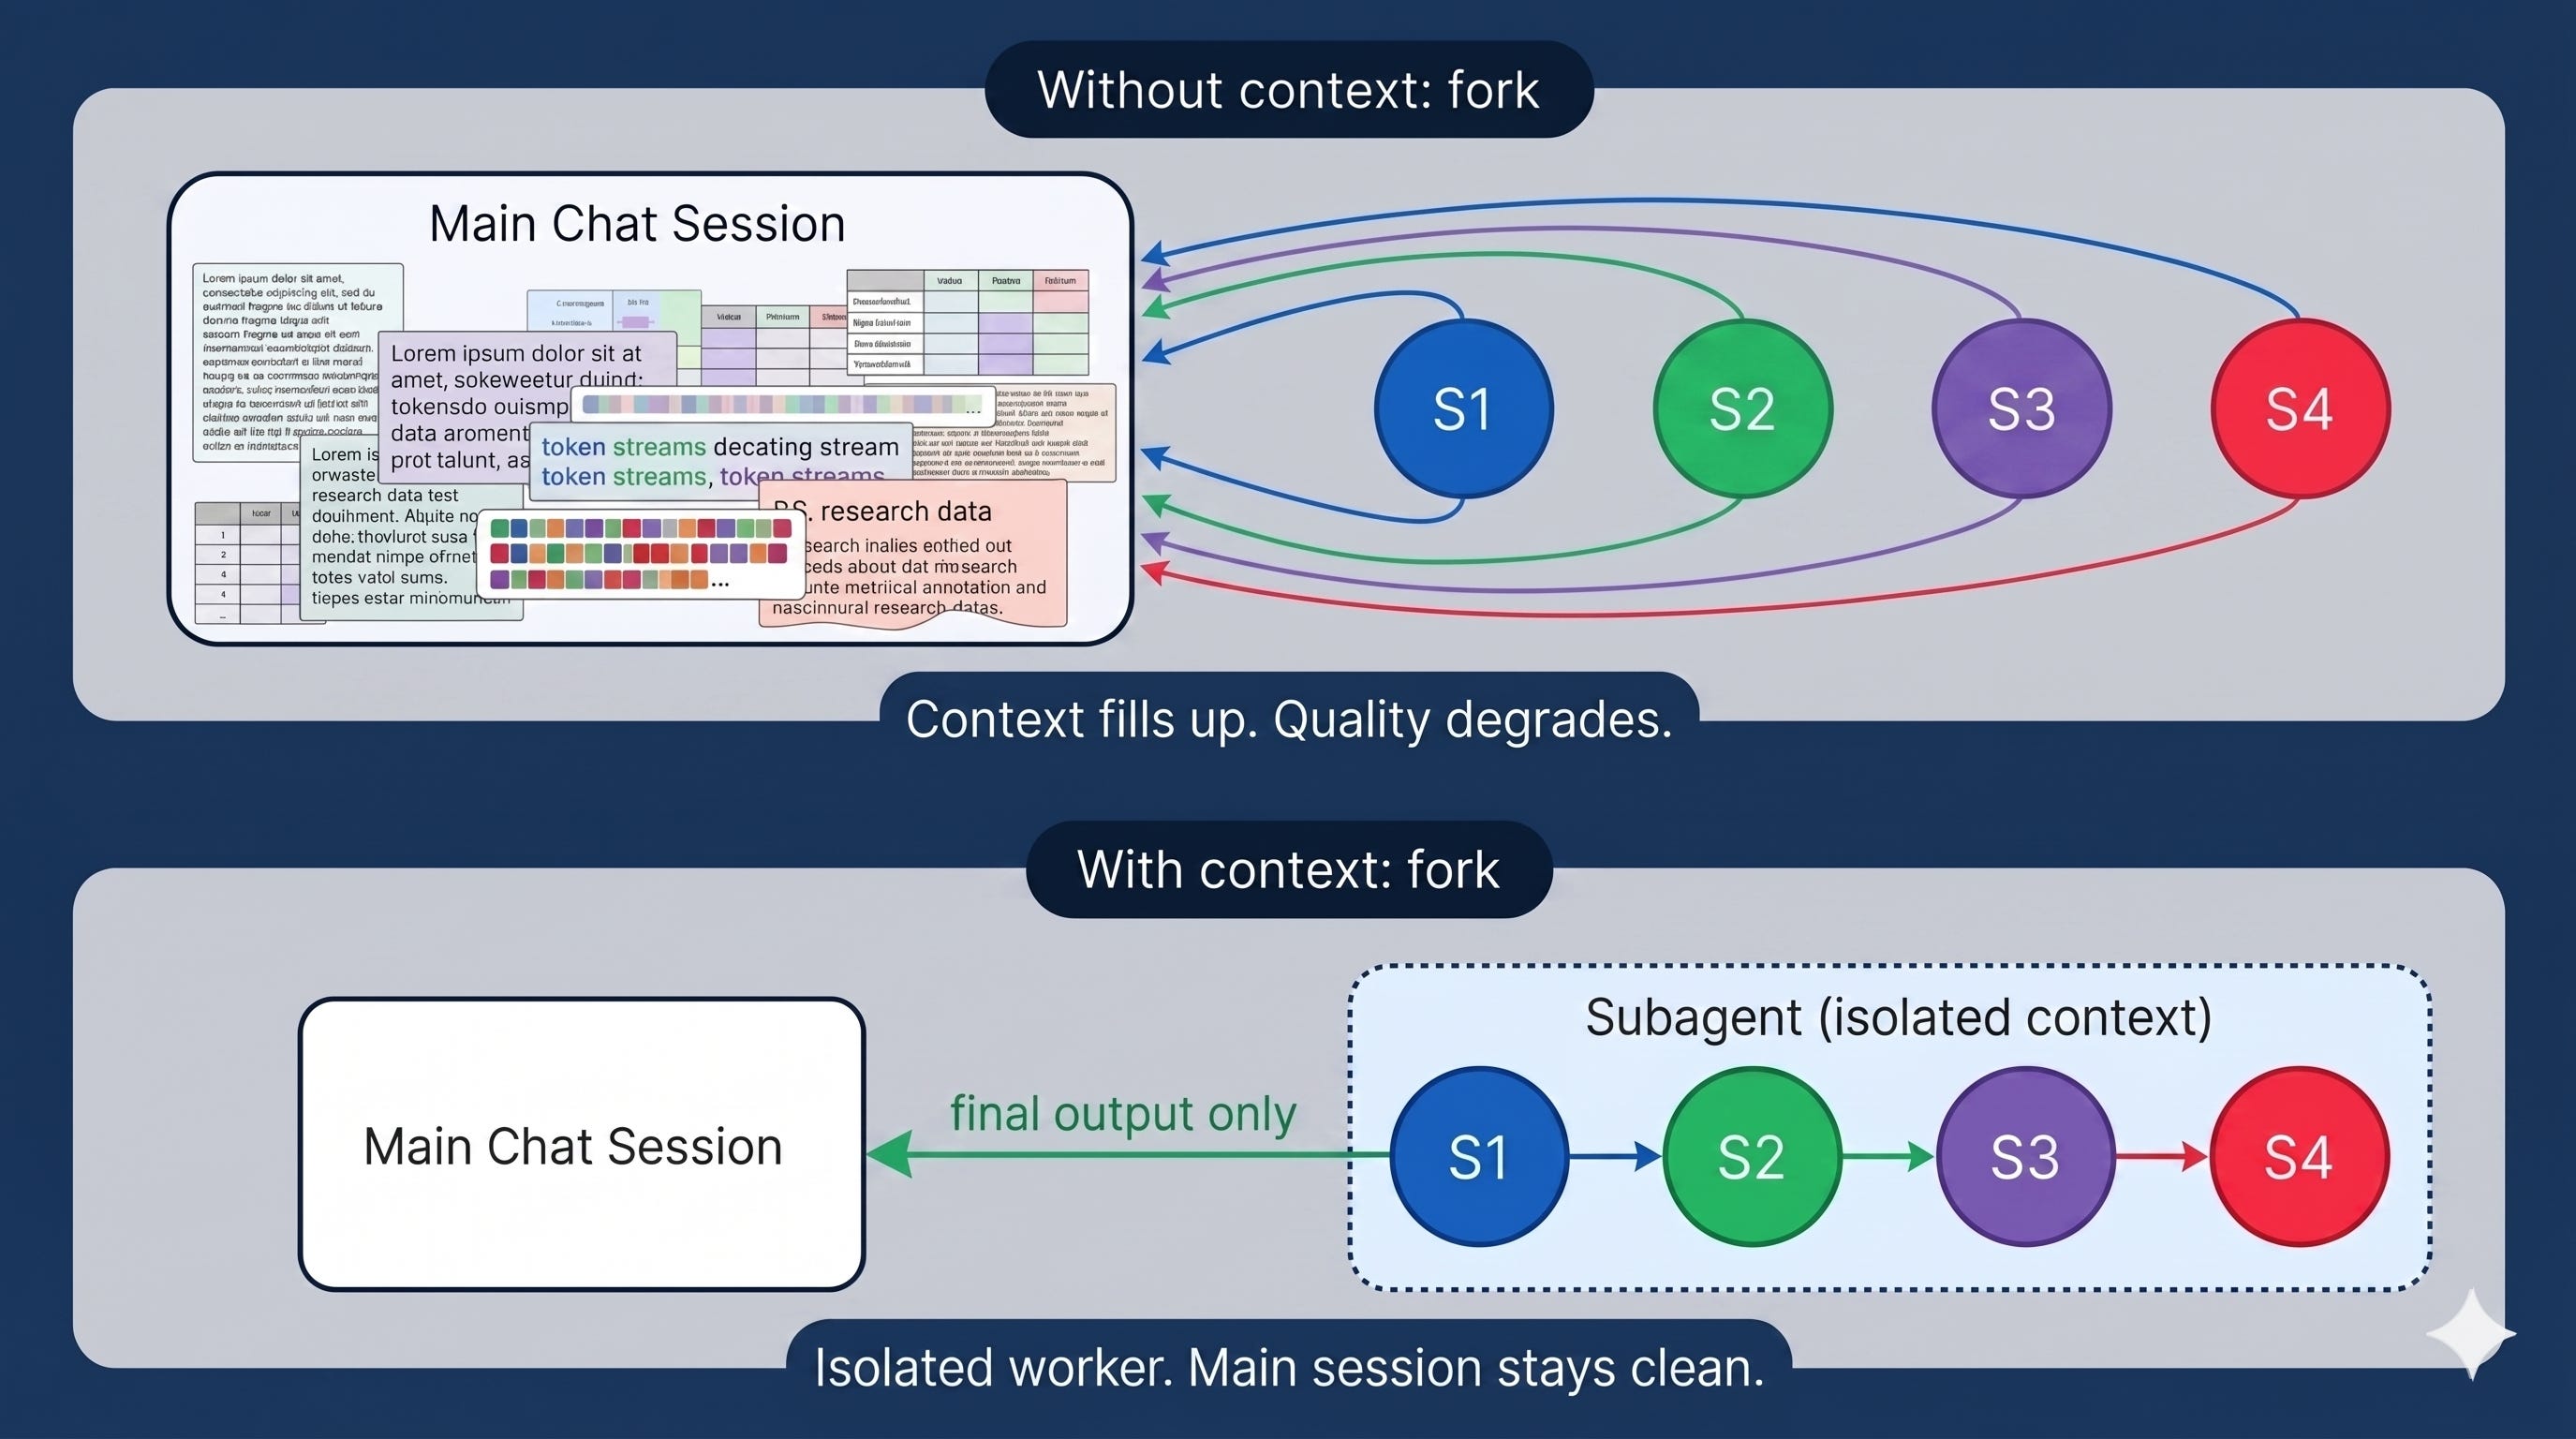
Without context: fork, all intermediate processing from every skill piles up in your main conversation. A four-skill pipeline researching three companies can produce 10,000+ tokens of intermediate work: raw research data, curation tables, draft prose. That’s your context window filling up with material you never need to see. With context: fork, none of it touches your session. You get the finished report.
A simplified orchestrator:
---
name: my-pipeline
description: Runs three skills in sequence
context: fork
---

Step 1: Run /research-skill to gather raw data.
Step 2: Run /analysis-skill to interpret the data.
Step 3: Run /format-skill to produce the final report.
Return the final report as a single document.
Three lines of instruction. Three skills. One slash command to trigger it all.
One Command, Two Companies, One Report
Here’s what this looks like with a real pipeline.
I built four skills, each with one job:
/competitor-research: searches the web for a company’s pricing tiers, feature list, recent product updates, market positioning, funding history, and user reviews. Collects raw data from public sources. Returns structured findings with source URLs./intelligence-curator: takes the raw research and organizes it. One company? Structured profile with pricing grid, feature map, and funding timeline. Multiple companies? Side-by-side comparison grid with standardized pricing, feature matrix, and sentiment comparison./analysis-writer: turns the curated data into a narrative. Competitive landscape overview, pricing analysis, feature differentiation, strategic positioning assessment, momentum and trajectory, head-to-head verdict, and actionable recommendations. Writes like an analyst, not a press release./report-formatter: grammar cleanup, consistent heading levels, table of contents, executive summary tightened, methodology footnote added. Turns a good draft into a deliverable you’d attach to a strategy brief.
One orchestrator ties them together. Here’s the file that does it:
---
name: competitive-intel
description: Produces a competitive intelligence report for one or more companies. Pass company names as arguments.
context: fork
agent: general-purpose
disable-model-invocation: true
allowed-tools: Read Write WebSearch WebFetch Skill
---

Companies to analyze: $ARGUMENTS

Run the following skills in sequence to produce a complete competitive intelligence report.

Step 1: Run /competitor-research for each company listed above. Research each company individually. Collect all raw findings.

Step 2: Run /intelligence-curator to organize all findings from Step 1. If multiple companies were researched, structure the output as a comparison grid. If one company, structure as a single-company profile.

Step 3: Run /analysis-writer to produce a narrative analysis from the curated intelligence in Step 2. If multiple companies, include head-to-head comparison and strategic positioning assessment.

Step 4: Run /report-formatter to polish the analysis from Step 3. Fix grammar, tighten prose, add professional formatting, table of contents, and methodology footnote.

Return the final formatted report as a single markdown document.
Then I typed this:
/competitive-intel "Anthropic" "Google"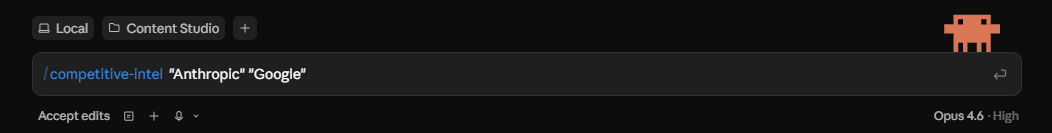
Switched to email. Came back to a formatted competitive intelligence report covering both companies. Pricing compared, features mapped against each other, strategic positioning assessed, specific recommendations at the end.
The report had:
An executive summary with the single biggest finding
A side-by-side snapshot table (founded, HQ, employees, funding, target market)
A pricing comparison grid standardized to monthly USD
A feature comparison matrix
A strategic positioning assessment for each company
A momentum section based on recent funding and product moves
A head-to-head verdict with no hedging
Actionable recommendations
A methodology footnote
Manually, this is half a day: four separate research sessions, a spreadsheet, an hour of writing, a formatting pass. The pipeline did it while I was doing other work.
If you want the full breakdown on how I run competitive research with Claude, separately from the pipeline, that’s here:

🔒 This is where the free section ends.
Paid subscribers get: the wizard skill that builds your custom pipeline (any workflow, any domain, any MCP connections), a look at the orchestrator file the wizard generates, and the debugging guide for when things break.
Build Your Own Pipeline in 10 Minutes
The competitive intelligence pipeline works for competitive analysis. Your workflow is probably different. Maybe you need a client proposal pipeline. A research-to-report pipeline. A weekly briefing pipeline that pulls data from Notion and formats it automatically.
Instead of handing you my specific pipeline files and asking you to modify them, I built something better.
/build-my-pipeline is a wizard skill. It interviews you about your workflow, then generates and installs every file you need: the orchestrator, every stage skill, the folder structure, and a test command.
