


Last week I published a deep dive on Cowork Plugins — what they are, the pre-built ones I tested, and how I built a custom plugin to fill a gap none of them covered.
If you missed it, the short version: Anthropic’s pre-built plugins are useful, but none could answer the one question I kept asking — “Is this new AI tool actually worth my time?”
So I built a custom evaluation plugin inside Cowork. It worked. But it was locked to my desktop, couldn’t be shared, and required Cowork to run.

The tool evaluation problem only accelerates. Perplexity just shipped an agentic computer use feature. Google dropped Gemini 3.1 Pro. Cursor, Windsurf, and Bolt are in an arms race. Every week I’m opening six tabs, skimming landing pages, hunting for pricing, reading two takes on social media, and still ending up unsure whether the tool fits my workflow, at my budget, for my use case. That loop takes 30–45 minutes per tool if I’m thorough. I’m rarely that thorough.
So I thought — why not build a tool that does all of this under one umbrella? Something that researches, scores, and gives an honest verdict, calibrated to who’s asking. Not a generic product summary. An evaluation that understands your context.
I built it as a Cowork plugin first to prove the concept. Then I vibecoded a proper frontend and backend — a real website anyone can access.
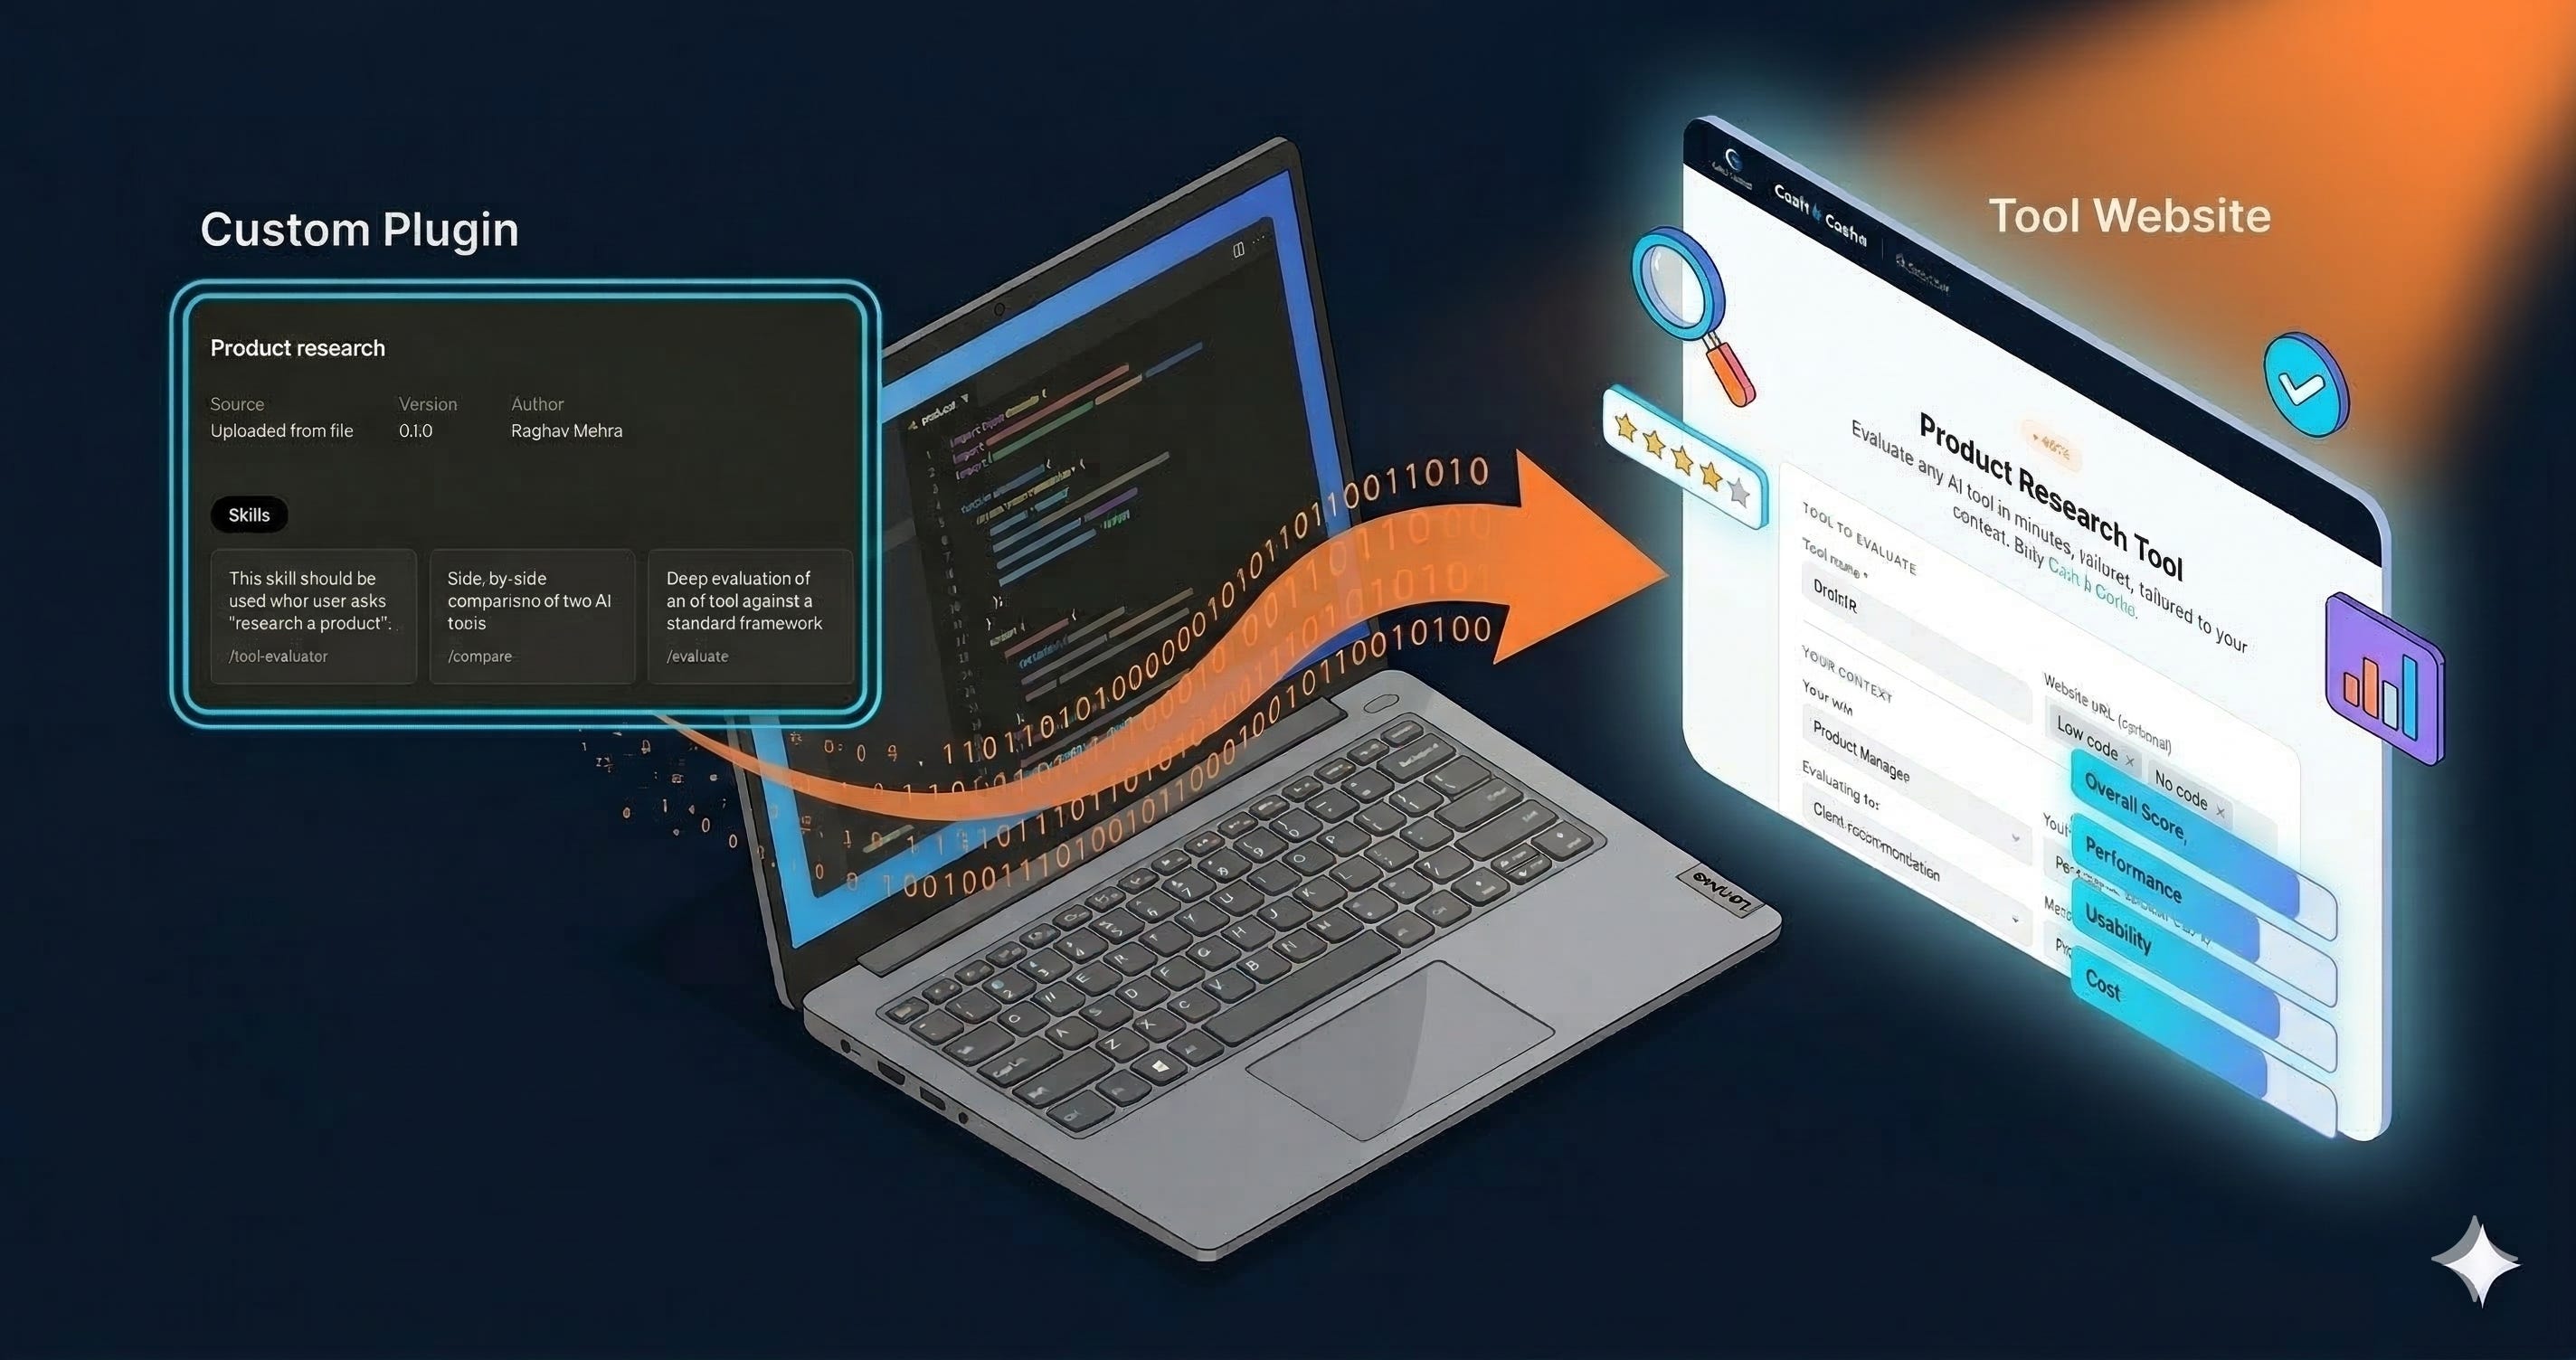
This is the story of what that week looked like:
What we’ll cover today...

What the tool does
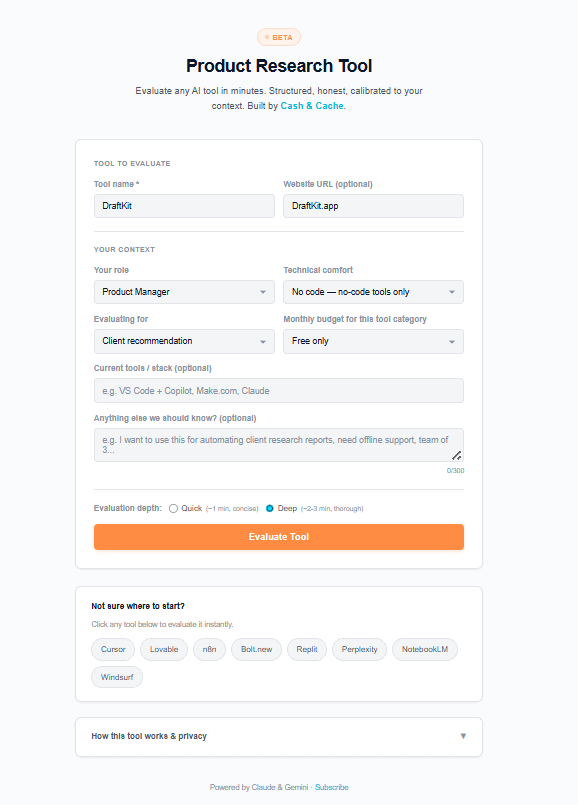
You tell it three things: what you want to evaluate, who you are, and what you’re evaluating for. It researches the tool, applies a consistent 8-dimension framework, and hands you a structured brief.
A PM evaluating Cursor for team adoption gets a different verdict than a solo founder evaluating it for personal prototyping. The facts don’t change — what matters does.
The eight dimensions: core capability, production readiness, pricing and value, API and integration quality, reliability at scale, data privacy, differentiation, and documentation. Each scored with a specific rationale you can click to expand. The output includes comparative strengths, consequence-based limitations, practical cost, alternatives with direct links, risks the marketing page won’t mention, and community opinions flagged as unverified.
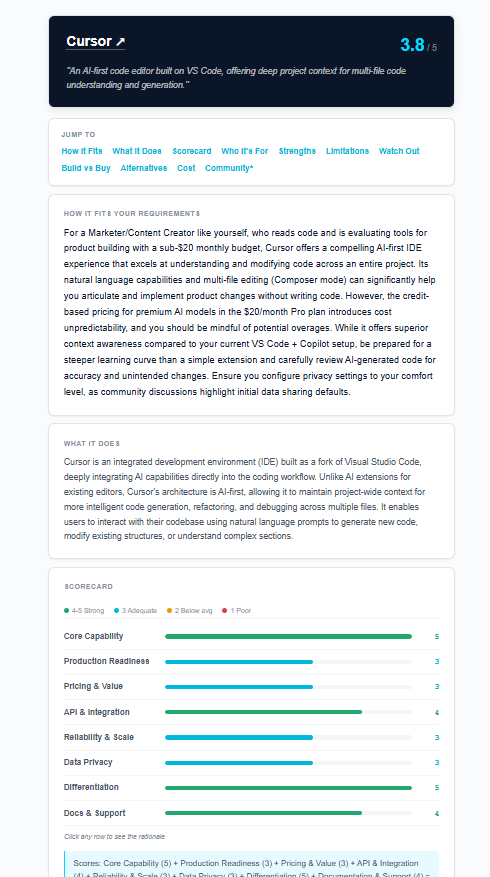
The section I’m most deliberate about: “How it fits your requirements.” It references your role, your budget, your stack, and tells you plainly whether this tool is worth your time.
Free version handles one-off evaluations. Paid subscribers unlock something different: frameworks you can build yourself, tracking over time, and direct access to our products, including this one!
The build: stack and decisions
Three tools for this build (at least for now!)
Claude wrote most of the code. I described what I wanted — a serverless backend that calls an AI API with my evaluation framework as the system prompt, and a single-page frontend with a form and results renderer — and Claude produced the files.
I was vibecoding a tool to evaluate AI tools, using an AI tool. The recursion wasn’t lost on me😉.
GitHub stores the code. My last Git experience before this project was 6 months back when I vibecoded a housing platform, based on an existing WhatsApp group.
For this project, my first push attempt failed because I typed my repository name instead of my username. Then Git told me it didn’t know who I was. Then the push got rejected because the remote had a conflicting README. I ended up uploading files manually through GitHub’s web interface. Elegant? No. Functional? Yes.
Vercel hosts it. Free tier, serverless functions, auto-deploys from GitHub. API key as an environment variable, hit deploy, live URL in 60 seconds. Free hosting, free deployment. This part actually felt like magic.
product-research-tool/
 api
  /evaluate.js        ← Vercel serverless function (calls Gemini API)
 public/
  index.html         ← Frontend (single page, no framework)
 package.json
 vercel.json
 .env.example
The Chrome extension dilemma
My original plan was a Chrome extension — evaluate tools while browsing their websites. Clean and contextual.
I stopped myself. I needed to test whether the evaluation framework produced useful output before investing in extension packaging, manifest configs, and Chrome Web Store logistics. A website tests the core hypothesis fastest: one URL, anyone with the access code can use it, and the backend is identical — the same API endpoint the extension would call later.
I wasn’t throwing away work. I was sequencing: validate the framework → ship as a website on Vercel’s free tier → build the extension on top of the same API.
Website first, extension later.
What broke on day one
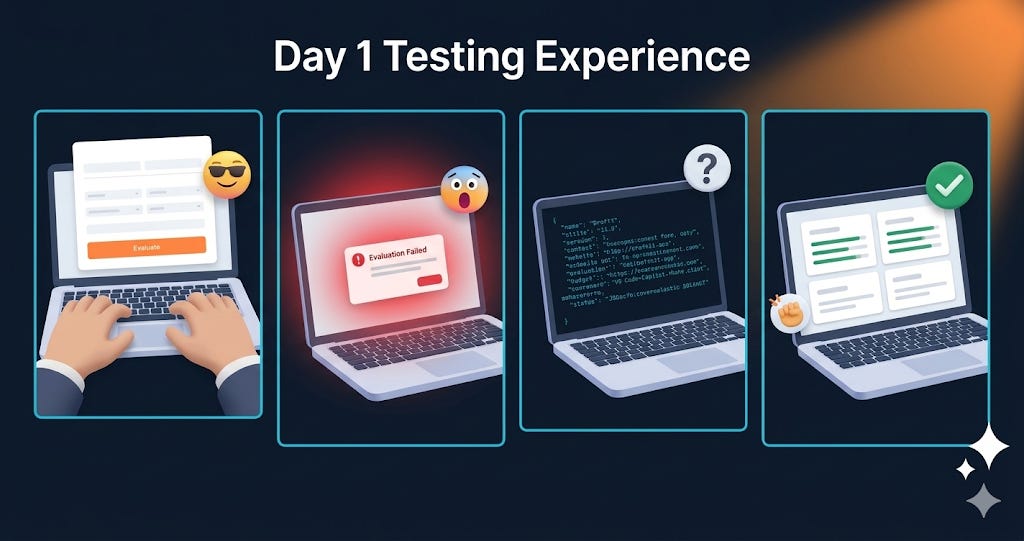
I opened the Vercel URL. Typed “Cursor.” Hit Evaluate.
“Evaluation Failed. Please try again.”
Vercel logs: 404 — model: claude-sonnet-4-6-20250514. Wrong model string. Changed it to the short format, redeployed, tried again.
This time it ran. Two minutes of loading. Then a wall of raw JSON appeared. Curly braces, quotation marks, nested objects. The evaluation was thorough — but it wasn’t readable.
The problem: the AI was returning thinking text before the JSON. My parser only stripped markdown fences but couldn’t handle the preamble. I added smarter extraction: find the first { and last }, parse only what’s between them. Redeployed. Clean, formatted cards appeared.
Two bugs, two fixes, one hour. The tool was live.
Before sharing the URL, I added an access code system — the URL includes a ?code= parameter. For security reasons— to prevent random traffic. No code, no access. However, the beta testers had this code listed and unlocked naturally when they clicked on the URL. The backend verifies on every request too. Simple, effective, and changeable in one environment variable.
What I found from beta testing
I shared the tool with eight paid subscribers and asked them to try it. Here’s what I discovered:
What I had to fix immediately
I realised the URL field had no validation when a test evaluation returned results for a football app instead of a design tool a beta tester entered — the URL was missing https:// and resolved to a completely different domain. Three lines of code: auto-prepend the protocol if it’s missing.
I noticed testers were abandoning before results loaded. There was no indication of how long the evaluation takes. I added a loading estimate: “This typically takes 2–3 minutes. Gemini is researching live data.” Abandonment stopped.
I found that the PDF download button didn’t fire on certain browsers. An email capture card I’d built was blocking the print dialog. The whole flow was too complex for a beta. I ripped it out entirely and replaced it with a single “Download PDF” button — desktop uses the print dialog, mobile generates an actual downloadable file via html2canvas + jsPDF.
What I hadn’t thought of
I’d placed the verdict at the bottom of the evaluation. After ten sections of detail. I heard back from a tester who said he was scrolling past everything to find the answer. Fair point. I moved “How it fits your requirements” to immediately after the header. Answer first, detail second.
The scorecard showed numbers without context. I understood the problem when I stared at a 2/5 on Production Readiness and couldn’t tell whether that was bad relative to the category or just bad in general. I added a colour-coded legend, clickable rows that expand to show rationale, and a hint: “Click any row to see the rationale.”
I also added a free-text field after realising the dropdown options couldn’t capture context like “I need offline support” or “migrating from Notion.” A 300-character text area, wired into the prompt so the evaluation actually calibrates against it.
What genuinely surprised me
I ran an evaluation on a free design tool and got a 3/5 on Pricing & Value. Despite the tool being free. The system was penalising it because the companion AI subscription cost money — but the budget field referred to the design tool category, not total software spend.
The evaluation was conflating the two.
I rewrote the budget label to “Monthly budget for this tool category” and added five explicit rules to the prompt: budget is category-specific, don’t penalise free tools for companion costs, flag companion expenses under “Watch Out” instead, never recommend paid alternatives when the user said “Free only.”
One ambiguous field label. Five prompt rules to fix it. This is the kind of thing you can’t catch testing your own tool.
I ensured the the evaluation report fit the user’s context and their professional requirements with a topline display of a summary of how the tool fits one’s requirement, its functions and the detailed scorecard:
The pivots I didn’t plan for
The feedback surfaced two decisions I hadn’t anticipated.
The output was too long. I agreed — you could cut it in half and still get the key insight. Instead of cutting globally, I added a Quick/Deep toggle.
Quick mode: stripped-down prompt, 2–3 sentences per field, top 3 strengths/limitations, roughly half the tokens. Deep stays thorough. Users choose.
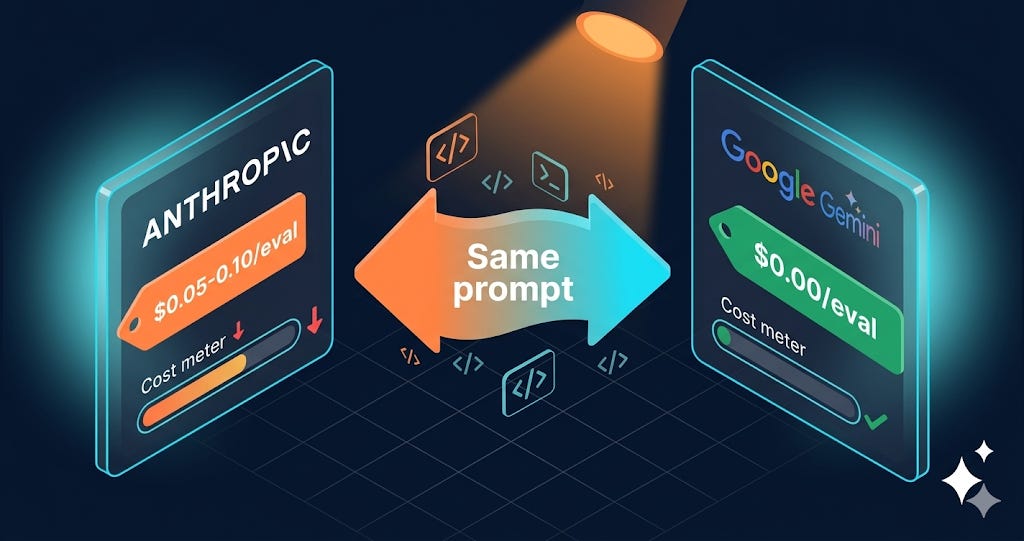
Then came the cost question. Claude Sonnet 4.5 costs $3/$15 per million tokens — roughly $0.05–0.10 per evaluation. Gemini 2.5 Flash has a free tier: 10 requests per minute, 250 per day. For a beta with 20–30 testers, that’s zero cost.
I rewrote the backend from the Anthropic SDK to Gemini’s REST API. The SDK failed on Vercel — module installation issues I couldn’t resolve. So I dropped it entirely and called Gemini’s API with fetch. Zero dependencies, zero module errors. The evaluation framework transferred unchanged because the intelligence lives in the prompt, not the code.
Trade-off: Gemini’s free tier occasionally 503s on Deep mode when servers are overloaded. Auto-retry is on the to-do list.
Improving output quality
After switching to Gemini, the first evaluations came back generic. Padded sentences. “It’s worth noting.” Strengths that said “Good performance” without comparing to anything. Limitations that named what was absent without saying what the user couldn’t do.
The tool was researching but writing like a press release.
This was a prompt engineering fix. I added seven non-negotiable writing rules to the system prompt: every sentence needs a specific detail. Seven filler phrases banned explicitly. Never parrot marketing language. Strengths must be comparative. Limitations must name the consequence. “Watch Out” must contain info not on the product page. The bottom line must read like advice from a colleague, not a product review.
Same API. Same model. Forty lines of prompt changes, zero code changes. Output quality improved immediately.
All of this — research, scoring, prompt refinement — lives inside evaluations. Paid tier lets you build the framework once and reuse it everywhere. More details on what lies on our Premium version:

Where it stands after one week
Evaluates any AI tool against 8 dimensions, calibrated to the user’s context. Quick mode: ~1 minute. Deep mode: 2–3 minutes. Results include a context-specific verdict, clickable scorecard, comparative strengths, practical cost, alternatives with direct links, and community opinions flagged as unverified.
Hosted on Vercel’s free tier. Powered by Gemini 2.5 Flash’s free tier. Costs me nothing to host and nothing to run.
What’s still broken: Deep mode occasionally 503s. Community opinions sometimes quote Reddit verbatim instead of summarising. The overall score should be a calculated average — Gemini sometimes eyeballs it but I am adding more quality guardrails each day.
What’s next: Compare mode (two tools side by side). Chrome extension (original plan, now informed by a week of beta). Open access once output quality stabilizes. A designed logo for this tool.
And many more improvements that I have not yet planned!
What I learned building this
Prompt engineering is 60% of the product. The code is plumbing — a form, an API call, a results renderer. The framework, the rubric, the anti-filler rules — that’s the product. When the output was generic, I changed 40 lines of prompt. Quality improved immediately.
Switching APIs mid-build is less scary than it sounds. Claude to Gemini in an afternoon. The framework transferred directly because it was a system prompt, not code logic.
Ship the simplest version and let users tell you what’s missing. I agonised over email capture, compare mode, a Chrome extension. My testers asked for a loading estimate, a scorecard legend, and a free-text context field. The features that mattered weren’t the ones I’d planned.
Thank you to the beta testers 💕
This tool is meaningfully better because of the people who took the time to use it, question it, and tell me what wasn’t working in its first week of beta launch.
🔷 Dr Sam Illingworth pushed me hardest on the output — too long, too expensive, switch APIs. He was right on all three. The Quick/Deep toggle and the Gemini migration both came from his feedback.
🔷 Karen Spinner caught the UX gaps I’d walked past — no loading estimate, no way to add custom context. Both are now core features.
🔷 Elena | AI Product Leader found the URL validation bug that caused the tool to evaluate a football app instead of a design tool. Three lines of code, one critical fix.
🔷 Joel Salinas flagged the broken PDF download and asked for a table of contents. Both shipped.
🔷 Daria Cupareanu’s budget test uncovered the most subtle bug — a field label ambiguity that caused the evaluation to penalise a free tool. Five prompt rules fixed it.
🔷 Mia Kiraki 🎭 gave me her honest assessment about how the user input fields in evaluation can be improved and was focal in identifying quality gaps in output after I switched API endpoints from Anthropic to Gemini.
🔷 Ashwin Francis pointed out the scorecard was numbers without meaning. The colour-coded legend and expandable rationale came from our conversation.
Every bug report and suggestion shaped what you see today. I’m happy to see more beta testers trying out this tool as I write.
Watch it in action 🎥
I recorded a walkthrough showing the full evaluation flow — filling in the form, the loading state, results appearing, expanding the scorecard, clicking alternative links, and downloading the PDF.
Paid subscribers of Cash & Cache get full access to testing now and using this tool in future. However, if you want to beta test this tool too, send me a DM and I’ll send you the details. ✨
I’ve been calling it Product Research Tool since the beginning. But I feel AI Tool Evaluator might be a sharper name — it says exactly what the tool does without the generic “product research” framing.
I’m genuinely torn. So I’m putting it to you.
Vote below. The winning name ships in the next update.
Have a tool you want evaluated? Feedback on what we’ve built? Drop a comment— the best suggestions shape what we build next. 💬
💡 Enjoying this article or other ones about practical implementation on AI? Share this piece with someone who can benefit.
We build these tools so that you don’t have too. More developments on this tool next week! ⚙️
This is really neat! I loved how you went into deleted on the build.
So exciting, congrats on the launch!